
Datacenter flagship · Hopper · launched 2023 · prices checked 2026-09-14
Rent NVIDIA H100 NVL — 80 GB, $1.811/hr on-demand
- VRAM 80 GBHBM3
- FP16 tensor 835TFLOPS
- PowerScore 588RTX 3090 = 100
- Configs 1–4×NVLink
- Online now 7 2 regions
Billed per second, price locked at deploy. Storage $0.08/GB/mo · bandwidth $0.01/GB — the whole fee schedule. Next weekly market re-check: 2026-09-21.
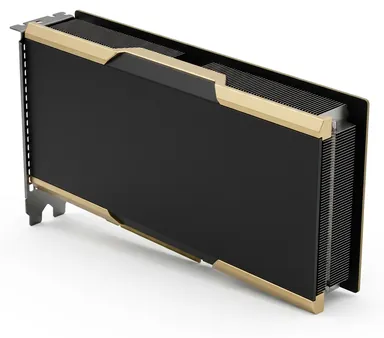
Datacenter flagship · Hopper architecture
The H100 NVL is the PCIe Hopper card tuned for inference: higher clocks and more bandwidth than the plain H100 PCIe, sold in NVLink-bridged pairs for serving 70B-class models across two cards. Rent it for Hopper serving throughput on PCIe hosts.
This is training-grade silicon: HBM3 memory feeding tensor cores at multi-TB/s, NVLink for scaling past one card, and the reliability profile of Tier-III datacenter hosts. Teams rent it for pre-training, long fine-tunes and high-throughput inference where batch size is money.
NVIDIA H100 NVL specs: VRAM, TFLOPS, bandwidth
| GPU model | NVIDIA H100 NVL | Architecture | Hopper (2023) |
|---|---|---|---|
| VRAM | 80 GB HBM3 | Memory bandwidth | 3,900 GB/s |
| FP16 tensor perf. | 835 TFLOPS | FP32 perf. | 60.0 TFLOPS |
| CUDA cores | 14,592 | TDP | 400 W |
| PowerScore (RTX 3090 = 100) | 588 | PCIe generation | Gen 5.0 |
| Multi-GPU | 1× – 4× · NVLink | Max instance storage | 12,000 GB NVMe |
| Network up to | 10,000 Mbps | CUDA | 12.4 – 13.0 |
Bandwidth, CUDA cores, TDP and FP32 are public NVIDIA figures; FP16 tensor is the dense (non-sparsity) number. Machine-level values come from live inventory.
H100 NVL price per hour: on-demand, interruptible, reserved
One public rule sets every price on this page: the marketplace median for the H100 NVL ($2.59/hr, snapshot 2026-09-14) × 0.70, rounded down — so on-demand is $1.811, 30% below market. Interruptible halves it; a 3-month reservation takes another 35% off.
| Mode | Per GPU-hour | Per day (24 h) | Per month (730 h) | What you get |
|---|---|---|---|---|
| On-demand | $1.811 | $43.46 | $1,322 | Guaranteed capacity, price locked at deploy, stop anytime |
| Interruptible | $0.905 | $21.72 | $661 | Flat −50%; may pause under capacity pressure, disk kept, auto-requeue |
| Reserved (3 months) | $1.177 | $28.25 | $859 | −35% on on-demand, rate locked for the term, capacity held |
Per GPU: an 4× machine costs exactly 4× — no multi-GPU premium. Estimate a full month with storage and bandwidth in the GPU cost calculator.
What you can run on a H100 NVL (80 GB VRAM)
With 80 GB of HBM3, a single card holds a ~32B-parameter LLM in FP16 or up to ~123B parameters quantized to 4-bit, with room for KV-cache at practical context lengths. Scale to 4× GPUs on one machine with NVLink for bigger models or bigger batches — the per-GPU price stays $1.811.
- One-click template: vLLM on a H100 NVL
- One-click template: PyTorch NGC on a H100 NVL
- One-click template: Axolotl — Fine Tuning on a H100 NVL
- Sizing help: LLM VRAM requirements guide
H100 NVL availability by region
7 × H100 NVL across 3 machines, live from inventory:
 Tokyo
 Stockholm
H100 NVL vs alternatives: price per TFLOP
| GPU | VRAM | FP16 | On-demand | $ / TFLOP-hr |
|---|---|---|---|---|
| H100 NVL this card | 80 GB | 835 | $1.811 | $2.17‰ |
| H100 PCIE | 80 GB | 756 | $1.867 | $2.47‰ |
| H200 NVL | 141 GB | 835 | $2.650 | $3.17‰ |
| A40 | 48 GB | 144 | $0.765 | $5.31‰ |
| L40S | 48 GB | 362 | $0.514 | $1.42‰ |
‰ = dollars per 1,000 TFLOP-hours of FP16 — a rough value-for-compute yardstick across cards.
- H100 NVL vs H100 SXM — specs, price per hour, which to rent
- All GPU comparisons
Renting a H100 NVL: frequently asked questions
How much does it cost to rent an NVIDIA H100 NVL per hour?
$1.811 per GPU-hour on-demand — a fixed price set at least 30% below the current market median of $2.59. Interruptible capacity costs $0.905/hr and a 3-month reservation $1.177/hr. Around $1,322/month if you keep one running non-stop, billed per second.
What can a H100 NVL with 80 GB VRAM run?
In LLM terms, roughly a 32B-parameter model in FP16 or up to ~123B parameters 4-bit quantized on a single card, with context headroom. Multi-GPU instances (up to 4× on current inventory) multiply that; diffusion and rendering workloads fit comfortably at this VRAM class.
Is the H100 NVL available to rent right now?
Yes — 7 GPUs across 3 machines in 2 regions are listed as we render this page. Configurations go from 1× to 4× with NVLink on multi-GPU chassis. Deploy from the console and it is running in about 30 seconds.
How do I deploy a H100 NVL?
Create an account (email + password, no card, no KYC), top up in crypto, open the console, filter by H100 NVL, pick a machine and a template such as PyTorch, vLLM or ComfyUI. The same deploy is one command with the CLI: powergpu launch --gpu h100-nvl --template pytorch.
Why is the H100 NVL cheaper here than on GPU marketplaces?
We price from the public marketplace median and fix our on-demand rate at least 30% below it, rounded down. The price is re-checked weekly (next check 2026-09-21) and published — no auctions, no per-host roulette, no bidding.