
Compare · prices checked 2026-09-14
H200 vs H200 NVL: specs, price per hour, which to rent
NVIDIA H200 (141 GB, $2.791/hr) against NVIDIA H200 NVL (141 GB, $2.650/hr): public specs side by side, live fixed prices from our sheet, what fits in each card's VRAM, and a verdict written for real workloads — both are rentable right now.
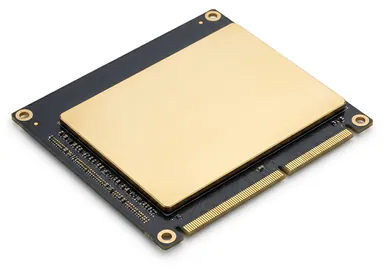
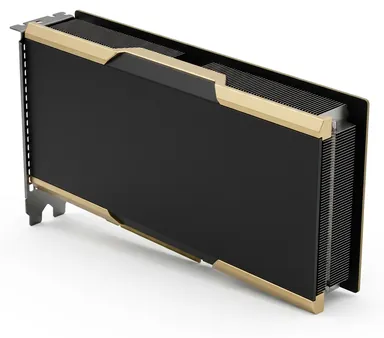
H200 vs H200 NVL specifications
Public NVIDIA figures (dense, non-sparsity). The last column is H200 relative to H200 NVL.
| Spec | H200 | H200 NVL | Difference |
|---|---|---|---|
| Architecture | Hopper (2023) | Hopper (2024) | — |
| VRAM | 141 GB HBM3e | 141 GB HBM3e | same |
| Memory bandwidth | 4,800 GB/s | 4,800 GB/s | same |
| FP16 tensor (dense) | 990 TFLOPS | 835 TFLOPS | +19% |
| FP32 | 67.0 TFLOPS | 60.0 TFLOPS | +12% |
| CUDA cores | 16,896 | 16,896 | same |
| TDP | 700 W | 600 W | +17% |
| PCIe · NVLink | Gen 5.0 · no NVLink | Gen 5.0 · NVLink | — |
| PowerScore (RTX 3090 = 100) | 697 | 588 | +19% |
| Max GPUs per machine | 8× | 8× | — |
H200 vs H200 NVL price per hour
Fixed rates from our sheet — every on-demand price is the marketplace median × 0.70, rounded down. Monthly = 730 hours.
| Rate | H200 | H200 NVL | Cheaper |
|---|---|---|---|
| On-demand, per GPU-hour | $2.791 | $2.650 | H200 NVL (−5%) |
| Interruptible, per GPU-hour | $1.395 | $1.325 | H200 NVL |
| Reserved (3 mo), per GPU-hour | $1.814 | $1.722 | H200 NVL |
| On-demand, per month | $2,037 | $1,935 | H200 NVL |
| Market median (reference) | $3.99 | $3.79 | — |
| $ per 1,000 FP16 TFLOP-hours | $2.82 | $3.17 | H200 (better value) |
| $ per GB of VRAM per hour | $0.0198 | $0.0188 | H200 NVL (better value) |
Try a full month with storage and bandwidth in the GPU cost calculator.
What fits in VRAM: 141 GB vs 141 GB
| Workload | H200 | H200 NVL |
|---|---|---|
| Largest LLM in FP16, one card | ~49B | ~49B |
| Largest LLM at 4-bit, one card | ~141B | ~141B |
| Flux dev (FP8, ~17 GB) | fits | fits |
| Wan 2.x 14B video (offloaded) | yes | yes |
| 70B 4-bit LLM on one card | yes | yes |
Rules of thumb: ~2.4 GB per billion parameters in FP16 all-in, ~0.62 GB in 4-bit. Full tables in the VRAM guide.
Verdict: which should you rent?
Same 141 GB of HBM3e: the SXM H200 offers 700 W, 8-way NVLink and slightly higher clocks; the H200 NVL is a PCIe card in bridged sets of two or four. NVL is cheaper per hour for inference; SXM for large training jobs.
- Cheaper per hour: H200 NVL ($2.650 vs $2.791, −5%).
- More VRAM: H200 (141 GB vs 141 GB).
- More FP16 throughput: H200 (about 1.2×).
- Best value per TFLOP-hour: H200.
- Best value per GB of VRAM: H200 NVL.
- Multi-GPU: H200 over PCIe · H200 NVL with NVLink.
H200 vs H200 NVL: FAQ
Deeper reading: H100 vs H200 vs B200, RTX 4090 vs RTX 5090, how cloud GPU pricing works.
Is the H200 faster than the H200 NVL?
On dense FP16 tensor throughput the H200 leads by about 1.2× (990 vs 835 TFLOPS). Memory bandwidth matters as much for inference: H200 4,800 GB/s vs H200 NVL 4,800 GB/s.
Which is cheaper to rent, the H200 or the H200 NVL?
The H200 NVL: $2.650/hr on-demand versus $2.791/hr — 5% less. Interruptible rates are $1.395 (H200) and $1.325 (H200 NVL). Per TFLOP-hour the better value is the H200.
Which has more VRAM and what does that change?
The H200 has 141 GB versus 141 GB. In LLM terms that is roughly a 49B FP16 model (or ~141B in 4-bit) on one card against 49B FP16 (~141B 4-bit). If the model does not fit, speed is irrelevant.
Can I rent both on PowerGPU right now?
Yes — 50 × H200 and 27 × H200 NVL are online as this page renders, deployable in about 30 seconds, billed per second, paid in crypto with no KYC.